Описание
Trafilatura — проверенный инструмент извлечения главного текста страницы. Убирает меню, рекламу и шаблоны, возвращает чистый текст с метаданными и поддерживает фоновую загрузку архивов для корпусов данных.
Что умеет:
— извлекать основной текст веб-страниц;
— собирать метаданные и комментарии;
— работать пакетно с архивами страниц;
— экспортировать в JSON, XML, CSV.
Полная документация ниже — автоматически из репозитория adbar/trafilatura (ветка master). Оригинальные материалы проекта распространяются на условиях его лицензии.
Trafilatura: Discover Web Content, Extract Text and Metadata



>>> from trafilatura import fetch_url, extract
>>> downloaded = fetch_url("https://github.blog/2019-03-29-leader-spotlight-erin-spiceland/")
>>> extract(downloaded)
'Erin Spiceland is a software engineer and ...'
>>> extract(downloaded, output_format="json", with_metadata=True)
'{"title": "Leader spotlight: Erin Spiceland", "author": "Jessica Rudder", "text": "Erin Spiceland is a software engineer and ..."}'
Introduction
Trafilatura is a comprehensive Python package and command-line tool
designed to gather text from the Web and turn raw HTML into structured,
meaningful data. It includes all necessary
discovery and text processing components to perform web crawling,
downloads, scraping, and extraction of main texts, metadata and
comments. It aims at staying handy and modular: no database is
required, the output can be converted to commonly used formats.
Going from raw HTML to essential parts, it focuses on the actual
content, avoids noise caused by recurring elements (headers,
footers, boilerplate), and makes sense of the data and metadata.
The extractor strikes a balance between limiting noise (precision) and
including all valid parts (recall). It is robust and reasonably fast.
Trafilatura is widely used
across thousands of projects,
including by HuggingFace, IBM, Microsoft Research, NVIDIA, the Allen Institute for AI, Stanford, and the Internet Archive.
Features
-
Advanced web crawling and text discovery:
- Support for sitemaps (TXT, XML) and feeds (ATOM, JSON, RSS)
- Smart crawling and URL management (filtering and deduplication)
-
Parallel processing of online and offline input:
- Live URLs, efficient and polite processing of download queues
- Previously downloaded HTML files and parsed HTML trees
-
Robust and configurable extraction of key elements:
- Main text (own rule-based extractor with jusText and readability-lxml as fallbacks)
- Metadata (title, author, date, site name, categories and tags)
- Formatting and structure: paragraphs, titles, lists, quotes, code, line breaks, in-line text formatting
- Optional elements: comments, links, images, tables
- Optional add-ons: language detection, speed optimizations
-
Multiple output formats:
- TXT and Markdown
- CSV
- JSON
- HTML, XML and XML-TEI
Evaluation
Trafilatura consistently outperforms other open-source libraries in text
extraction benchmarks. For more information see the
benchmark section
and the evaluation readme
to run the evaluation with the latest data and packages.
Other evaluations
- Most efficient open-source library in ScrapingHub‘s article extraction benchmark
- Best overall tool according to Bien choisir son outil d’extraction de contenu à partir du Web
(Lejeune & Barbaresi 2020) - Best single tool by ROUGE-LSum Mean F1 Page Scores in An Empirical Comparison of Web Content Extraction Algorithms
(Bevendorff et al. 2023)
Documentation
Getting started with Trafilatura
is straightforward. For more information and detailed guides, visit
Trafilatura’s documentation:
- Installation
- Usage:
On the command-line,
With Python,
With R - Core Python functions
- Interactive Python Notebook: Trafilatura Overview (in the repository)
- Tutorials and use cases
See the video tutorials playlist (multiple languages).
License
This package is distributed under the Apache 2.0 license.
Versions prior to v1.8.0 are under GPLv3+ license.
Contributing
Contributions of all kinds are welcome. Visit the Contributing
page
for more information. Bug reports can be filed on the dedicated issue
page.
Many thanks to the
contributors
who extended the docs or submitted bug reports, features and bugfixes!
Support
If you value this software or depend on it for your product, consider
sponsoring it and contributing to its codebase. Your support
on GitHub or ko-fi.com
will help maintain and enhance this package.
Context
This work started as a PhD project at the crossroads of linguistics and
NLP. This expertise has been instrumental in shaping Trafilatura over
the years. Initially launched to create text databases for research purposes
at the Berlin-Brandenburg Academy of Sciences (DWDS and ZDL units),
this package continues to be maintained and its future depends on community support.
Trafilatura is an Italian word for wire
drawing symbolizing the
refinement and conversion process. It is also the way shapes of pasta
are formed.
Author
Reach out via the software repository or the contact
page for inquiries, collaborations, or
feedback. See also social networks for the latest updates.
- Barbaresi, A. Trafilatura: A Web Scraping Library and Command-Line
Tool for Text Discovery and
Extraction, Proceedings
of ACL/IJCNLP 2021: System Demonstrations, 2021, p. 122-131. - Barbaresi, A. "Generic Web Content Extraction with Open-Source
Software",
Proceedings of KONVENS 2019, Kaleidoscope Abstracts, 2019. - Barbaresi, A. "Efficient construction of metadata-enhanced web
corpora",
Proceedings of the 10th Web as Corpus Workshop
(WAC-X), 2016.
Citing Trafilatura
Trafilatura is widely used in the academic domain, chiefly for data
acquisition. Here is how to cite it:

@inproceedings{barbaresi-2021-trafilatura,
  title = {{Trafilatura: A Web Scraping Library and Command-Line Tool for Text Discovery and Extraction}},
  author = "Barbaresi, Adrien",
  booktitle = "Proceedings of the Joint Conference of the 59th Annual Meeting of the Association for Computational Linguistics and the 11th International Joint Conference on Natural Language Processing: System Demonstrations",
  pages = "122--131",
  publisher = "Association for Computational Linguistics",
  url = "https://aclanthology.org/2021.acl-demo.15",
  year = 2021,
}
Software ecosystem
Jointly developed plugins and additional packages also contribute to the
field of web data extraction and analysis:
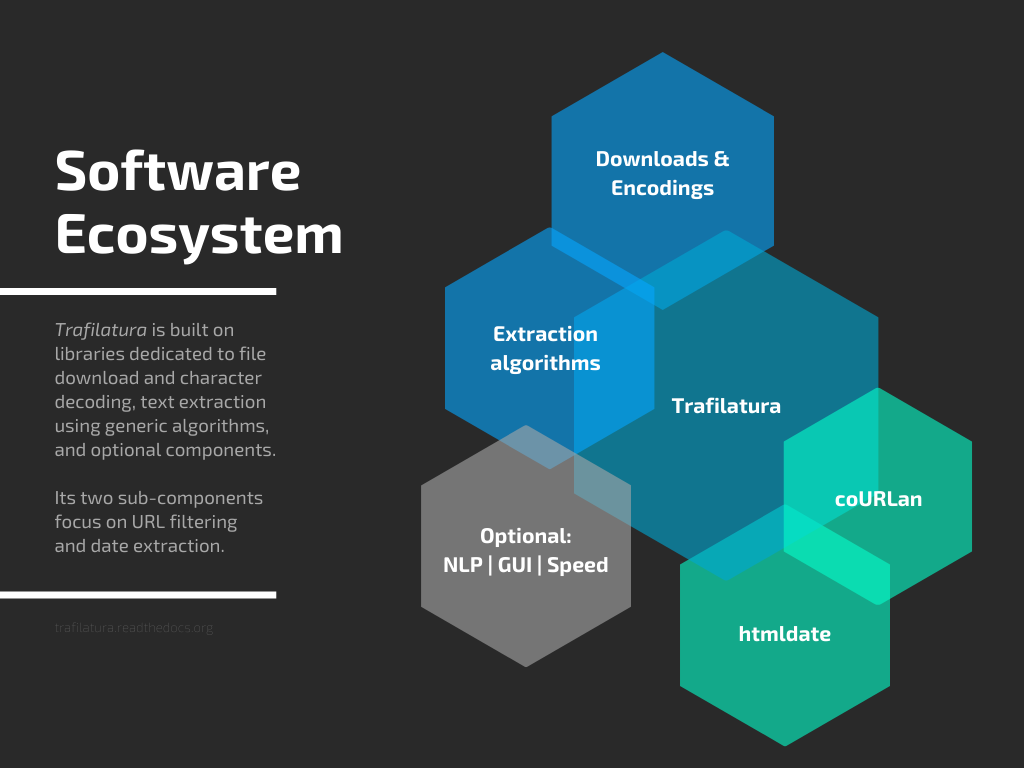
Corresponding posts can be found on Bits of
Language.